Web Scraping MCP Server: Giving AI Agents Direct Access to Live Web Data
Web ScrapingLearn how a Web Scraping MCP Server gives AI agents live web access while reducing token costs by 87% through structured extraction and visual selection.
A 403 Forbidden error stops revenue growth. For e-commerce intelligence teams, shifting to autonomous agentic systems often hits a structural bottleneck: the context window. Feeding raw HTML into a Large Language Model (LLM) is inefficient engineering that increases costs and reduces reasoning accuracy. High-margin data operations require moving away from redundant DOM boilerplate.
The honest verdict: why MCP is the new standard
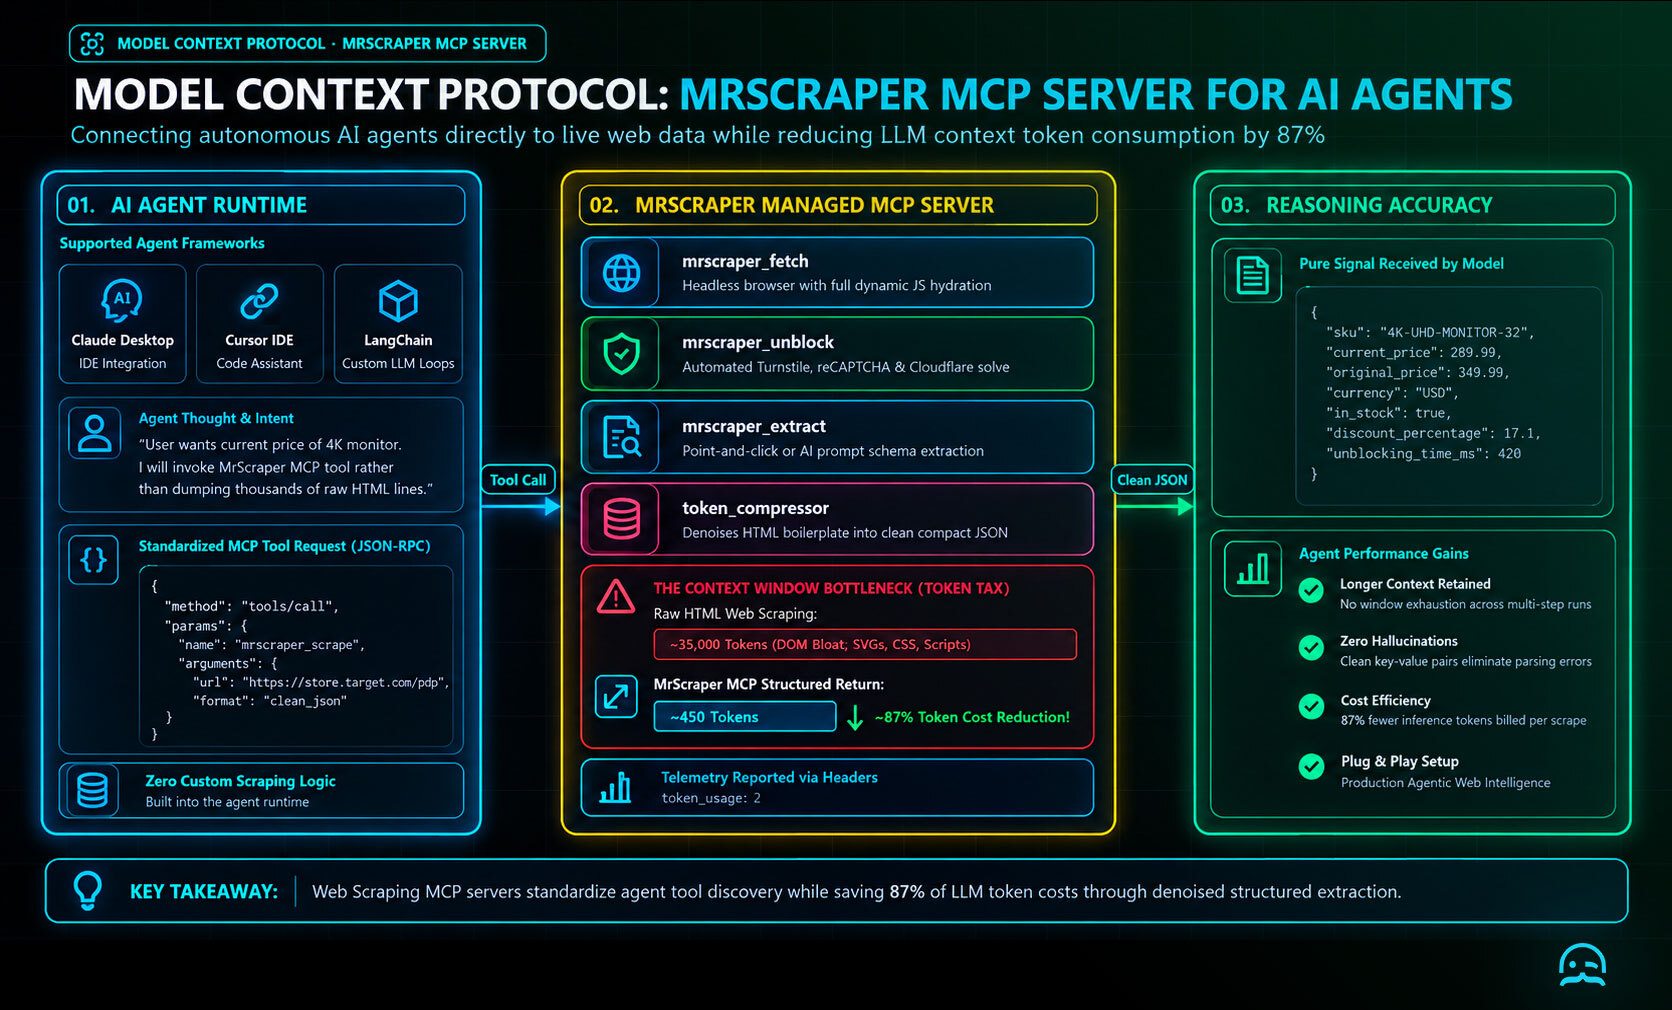
The Model Context Protocol (MCP) is a universal interface for AI. It is like USB-C, which standardizes hardware connections. It allows LLMs to interact with external tools without building custom integrations for every data source (Proxyway). By using an MCP server, an agent no longer guesses how to navigate a site. It calls standardized tools that handle fetching, unblocking, and parsing, returning only the specific signal needed for decision-making.
The token tax: raw HTML vs. structured stores
Traditional scraping methods fill context windows by forcing agents to process thousands of lines of code. Analysis of structured stores compared to raw payloads shows that high-performance configurations managing 800 rows of data via a store save 28,332 tokens (ScrapingBee). This architecture allows agents to maintain reasoning quality over longer sessions because the model ignores irrelevant elements. For intelligent data extraction, this compression is vital to avoid budget exhaustion. Teams automating data loops use this efficiency to protect margins.
Comparing MCP scraping implementations
Managed MCP endpoints provide abstraction that open-source scripts lack. While basic servers provide raw markdown, professional implementations like MrScraper offer visual selection and plain-English extraction. Standardizing these connections enables agentic tool discovery across domains. For example, some implementations provide over 70 tools for LLMs to access 190+ datasets across 120+ domains. Bright Data's MCP server specifically focuses on these pre-built datasets, whereas MrScraper allows for dynamic, visual definitions of new targets. Using AI-native search engines alongside these servers reduces costs by integrating extraction directly into the search process. To improve reliability, developers use a professional data scraping api to handle complex browser fingerprinting.
Feature comparison
| Feature | MrScraper MCP | Bright Data MCP | Open-Source Servers |
|---|---|---|---|
| Extraction Type | Visual & Plain English | Dataset-driven | Raw Markdown |
| Anti-Bot Management | Managed Residential | Managed Residential | Manual/Basic |
| Token Optimization | 87% Compression | High | Minimal |
Connecting your first web scraping MCP server
Configuring the environment for Claude and Cursor
- Generate an API token from your MrScraper dashboard.
- Open the Claude desktop configuration file in your App Support folder.
- Add the server entry to the
mcpServersJSON block. - Restart the client to enable the scraping tools.
{
  "mcpServers": {
    "mrscraper": {
      "command": "npx",
      "args": ["-y", "@mrscraper/mcp@latest"],
      "env": {
        "MRSCRAPER_API_KEY": "YOUR_API_TOKEN_HERE"
      }
    }
  }
}
Visual selection vs. brittle selectors
Many implementations rely on massive datasets or markdown dumps. A resilient approach uses visual selectors or natural language prompts to define targets. This ensures automated extraction pipelines remain functional when e-commerce sites update their front-end architecture. Replacing flaky browser scripts with semantic understanding allows a task-specialized AI architecture to handle requests for specific page types. The scrapingapi simplifies this process by abstracting the underlying infrastructure.
Technical advantages of managed MCP endpoints
Modern implementations enable 87% token-compressed web scraping optimized for LLM consumption (Glama). By offloading operational complexity to a managed endpoint, an agent uses semantic data extraction and:
- Automatic proxy rotation across residential IP pools to avoid rate limits.
- Integrated CAPTCHA bypass and headless browser api management.
- Real-device routing for high-entropy targets.
- Deterministic JSON output that maps to the agent's internal state.
import asyncio, os
from mrscraper import MrScraper

async def main():
    # Initialize client with environment variable
    client = MrScraper(token=os.environ["MRSCRAPER_API_TOKEN"])

    # Scrape an e-commerce listing with AI extraction
    target_url = "https://example.com/products/laptops"
    prompt = "Extract product names, current prices, and stock status."

    try:
        result = await client.create_scraper(
            url=target_url,
            message=prompt,
            agent="listing"
        )
        print(f"Scraper initiated. ID: {result['data']['data']['scraperId']}")
    except Exception as e:
        print(f"Scraping failed: {e}")

if __name__ == "__main__":
    asyncio.run(main())
The code above replaces hundreds of lines of selector logic. The agent asks for the data it needs, and the interface handles execution. This follows an agentic interface playbook that prioritizes autonomous supervision.
Frequently asked questions
What is MCP in AI and how does it work?
An MCP server is a standardized interface that acts as a translation layer. It sits between an LLM's natural language requests and the technical requirements of the web.
How does MCP reduce token costs?
Instead of sending a full 500KB HTML file to the LLM, the server parses the page locally and sends only relevant text or structured JSON. This reduces context window usage by up to 87%.
Next steps for developers
- Sign up for a MrScraper developer account to get an API token.
- Connect the tool to your local IDE or Claude desktop using the configuration above.
- Run a test scrape on a complex listing page to verify token savings using api web scraping.
MCP transforms web scraping from a brittle script into a standardized agentic tool. You can stop managing selectors and start managing insights by connecting your agents to a professional scraping control plane. Ready to optimize your data pipeline? Start a free trial today.
Summarize this post
Open it in your assistant of choice with the prompt ready to send.
Take a Taste of Easy Scraping!


Find more insights here
Scaling E-commerce Competitive Intelligence with Automated Data Harvesting
Scale e-commerce data harvesting with residential proxies and AI. Learn how modern data extraction s…
Scaling Data Extraction via AI-Driven Dynamic Selectors
Learn how AI-driven dynamic selectors and residential proxies reduce web scraping maintenance costs…
Why MrScraper is the Best ScraperAPI Alternative for No-Code Users
Compare ScraperAPI alternatives and discover why visual, AI-powered extraction is better for no-code…