MrScraper vs ScraperAPI: Which Scraping API Wins in 2026?
Web ScrapingCompare MrScraper vs ScraperAPI. Learn how AI-powered selectors and native scheduling reduce the total cost of ownership in web scraping.
You are paying a maintenance tax that ScraperAPI does not solve if you are still manually updating CSS selectors every time a target site changes its layout. For business analysts and lead generation specialists, the bottleneck has shifted from IP rotation to DOM maintenance. Success now depends on reducing the hours required to keep scrapers running without deep coding expertise.
What you'll learn:
- Why maintenance-free extraction is replacing simple proxy wrappers
- How AI-powered selectors reduce time spent on broken scrapers
- Technical comparison of feature sets and scheduling capabilities
- The true cost of ownership between visual tools and custom scripts
The verdict: MrScraper vs ScraperAPI
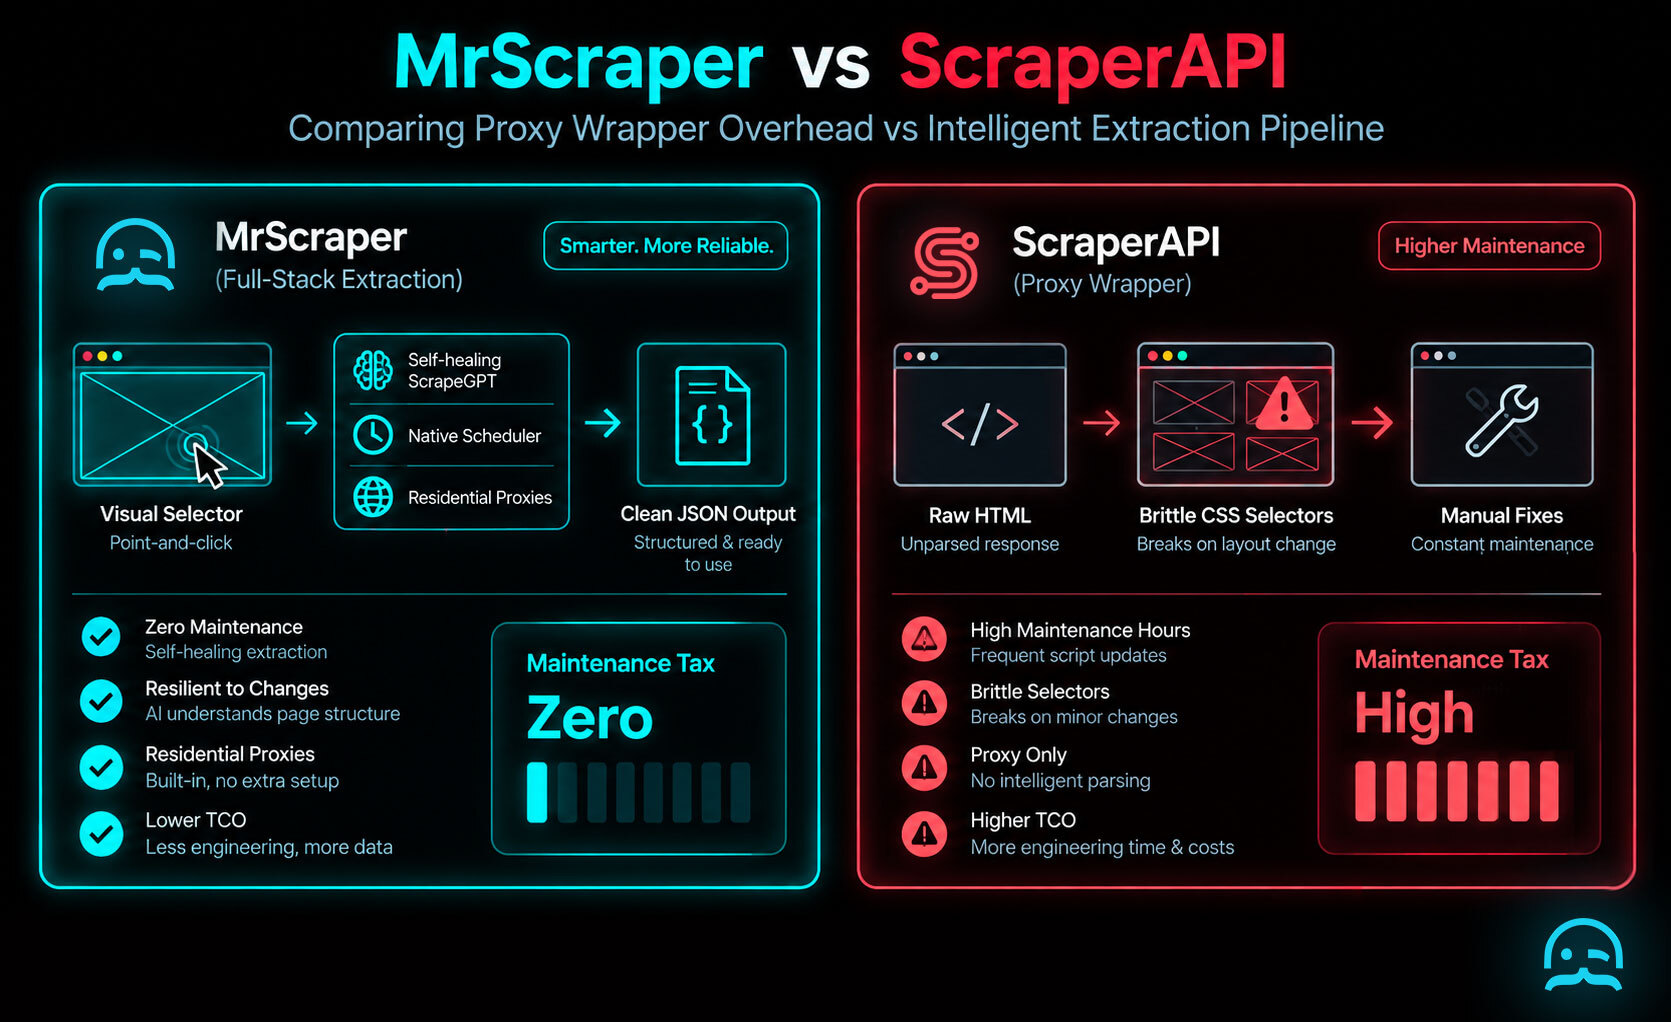
I analyzed both platforms for teams prioritizing efficiency. MrScraper offers a visual selector and AI extraction that reduces maintenance compared to ScraperAPI. While ScraperAPI is a solid proxy wrapper, MrScraper provides a native scheduler and self-healing selectors. These features lower the total cost of ownership for production-scale data pipelines.
Choosing a web scraping API for scalability
Feature comparison
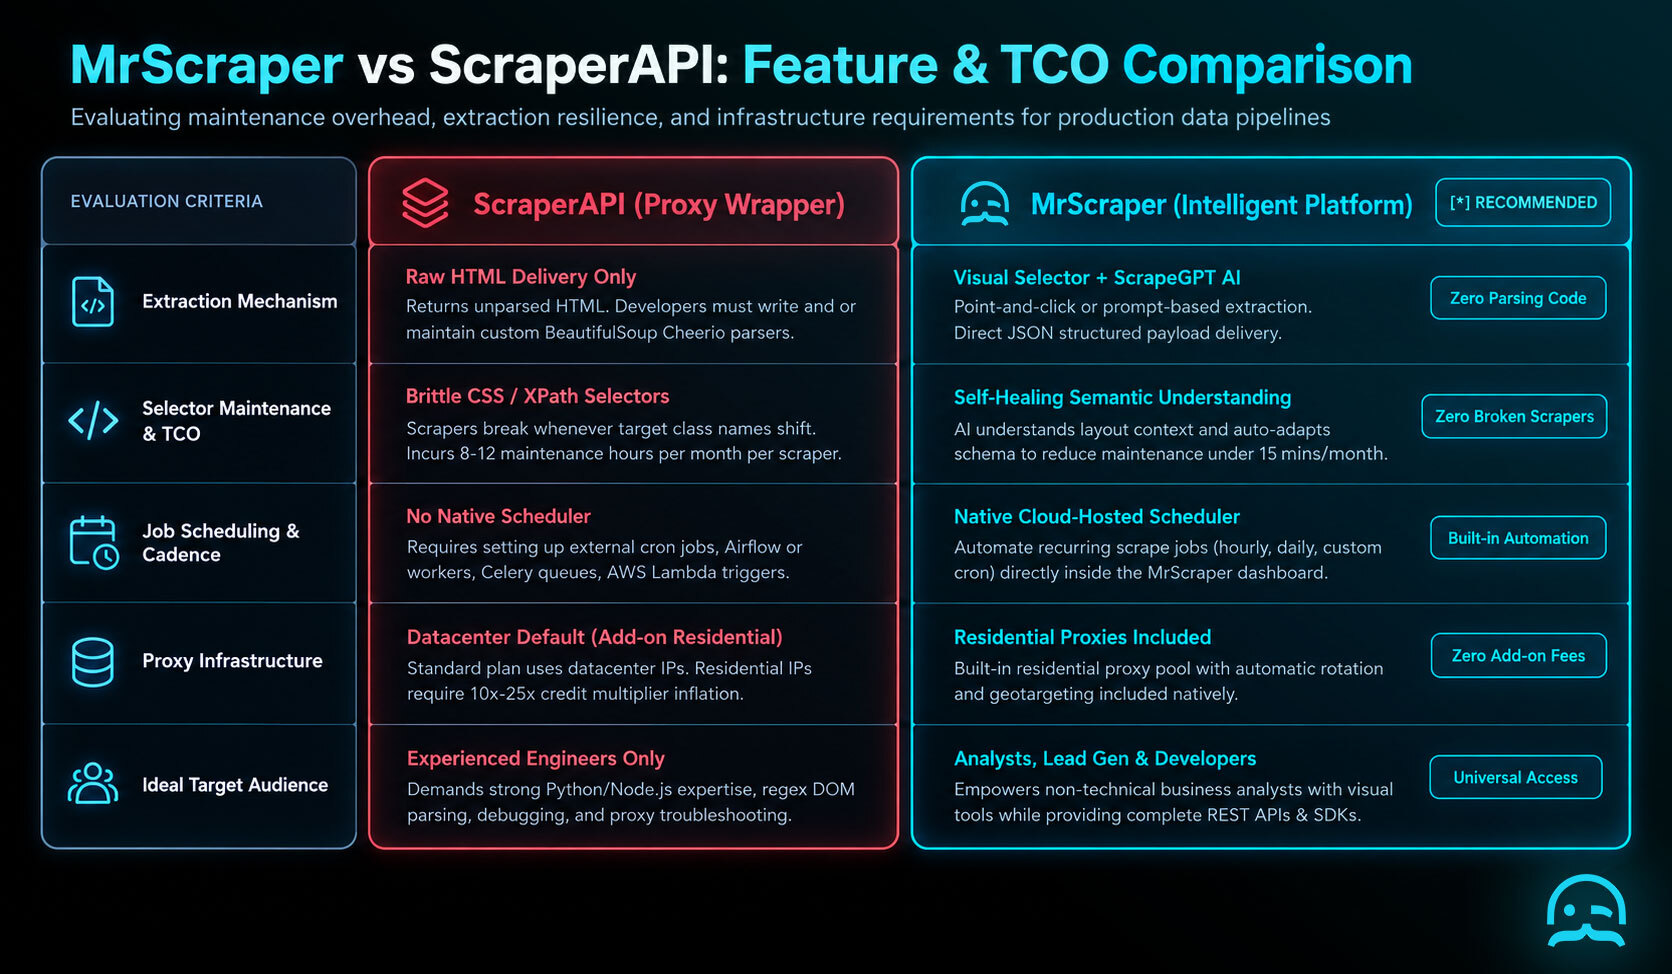
| Feature | ScraperAPI | MrScraper |
|---|---|---|
| Proxy Type | Datacenter/Residential | Residential Included |
| Visual Selector | No | Yes |
| Native Scheduler | No | Yes |
| AI Extraction | Limited | Full ScrapeGPT |
Total cost of ownership: Beyond the API credit
Analysts are moving away from legacy connection-only tools to find better handling for modern JavaScript-heavy sites and complex bot management layers (Scrape.do). When evaluating ScraperAPI alternatives, the real expense is not the credit cost. It is the time lost to fixing broken scrapers. If a site updates its layout and your scraper breaks, that is downtime your market research cannot afford.
The maintenance tax of brittle selectors
ScraperAPI requires you to maintain your own extraction logic. Every time a retailer changes a class name, you have to push a . This reflects the hidden cost of test automation (QA flow), where specialists spend significant time maintaining existing scripts rather than expanding coverage. Standard data extraction software often lacks the agility to handle dynamic e-commerce changes. MrScraper uses resilient AI-powered semantic understanding to keep the data flowing even when the site changes.
Handling modern bot management
- Success at scale requires managing TLS handshakes to mimic real browsers.
- Residential proxies are essential to handle ASN-based blocking.
- Headless browser orchestration is needed for dynamic content rendering.
- Automated reliable page access reduces failed request costs.
- JA4 browser checks handle is required for high-security targets.
While many look for modern ScraperAPI alternatives, the decision comes down to the trade-offs between building custom scrapers and managed APIs. For most, managed extraction APIs provide better auditability and lower maintenance than managing serverless containers or complex custom scripts. This is particularly relevant when performing a competitor price comparison across hundreds of different retail domains.
Visual scheduling vs. custom scripts
- Select your target URL and use the visual selector to pick data points.
- Set a recurring schedule within the dashboard (e.g., every 6 hours).
- Receive structured JSON data directly via webhook or API.
Frequently asked questions
Which is the best web scraping API for non-coders?
MrScraper is the superior choice for non-coders and analysts due to its visual interface and ScrapeGPT extraction tools. These eliminate the need for custom Python scripts.
How does MrScraper handle residential proxies?
MrScraper includes high-quality proxy rotation natively. This ensures high success rates on difficult targets without extra configuration. For teams needing AI-powered extraction and reliable page access, this integration is critical.
Key takeaways
- Maintenance time is the largest cost in web scraping.
- Visual tools and AI extraction solve the brittle selector problem.
- Managed scheduling reduces infrastructure overhead.
Reliable web data collection shouldn't be complicated.
MrScraper helps enterprise teams collect data at scale, including from websites that are difficult to extract. Now it's your turn to put it to the test.
Get 1,000 free tokens and try MrScraper here.
Summarize this post
Open it in your assistant of choice with the prompt ready to send.
Take a Taste of Easy Scraping!

Find more insights here
Claude Code Competitor Pricing Research
Use Claude Code and MrScraper MCP to refresh public competitor pricing, normalize billing periods an…
Use MrScraper MCP to Compare Public SaaS Pricing and Plan Limits
Build a source-backed SaaS plan comparison using MrScraper MCP. Preserve prices, quotas, billing ter…
Build a Product Attribute Classifier with LangChain and MrScraper
Build a LangChain workflow that extracts product evidence with MrScraper, normalizes attributes and…