Scraping with Node.js: A Practical Developer Guide
Web ScrapingLearn scraping with Node.js using Axios, Fetch, Cheerio, Puppeteer, and practical examples for static and JavaScript-rendered pages.
Scraping a website with Node.js means fetching web content with code. It also means parsing HTML. Then you extract structured data with tools like Axios, Cheerio, Fetch, and Puppeteer.
Why Choose Node.js for Web Scraping
Node.js is well suited for web scraping because:
- It handles I/O operations asynchronously, keeping scraping fast and efficient.
- JavaScript’s event-driven model makes concurrency easier without multi-threading complexity.
- The Node ecosystem includes many libraries for both simple and advanced scraping tasks.
- You can choose different tools depending on whether the site is static or heavily dynamic.
Essential Libraries for Scraping in Node.js
HTTP Clients
Node.js offers several ways to fetch HTML from a website:
- Native
http/httpsmodules – built into Node.js. - Fetch API – supported natively in Node 18+.
- Axios – Promise-based HTTP client with a clean API.
HTML Parsing
After fetching HTML, you need a parser:
- Cheerio – implements a jQuery-like API for server-side DOM traversal.
Headless Browsers
For JavaScript-rendered content:
- Puppeteer – controls Chromium/Chrome programmatically.
- Playwright – cross-browser automation library.
Example 1: Simple Scraper Using Axios and Cheerio
This approach works best for sites that return content in static HTML.
Step 1: Create a project and install dependencies
mkdir node-scraper
cd node-scraper
npm init -y
npm install axios cheerio
Step 2: Basic scraper code (scrape.js)
const axios = require('axios');
const cheerio = require('cheerio');

async function scrape() {
  try {
    const response = await axios.get('https://example.com');
    const html = response.data;
    const $ = cheerio.load(html);

    const headlines = [];
    $('h2').each((i, element) => {
      headlines.push($(element).text().trim());
    });

    console.log('Headlines:', headlines);
  } catch (error) {
    console.error('Error fetching page:', error);
  }
}

scrape();
How it works
axios.get()fetches the HTML.cheerio.load()parses it into a DOM-like structure.- CSS selectors extract the needed data.
Example 2: Using Node’s Native Fetch
Starting with Node 18, the Fetch API is available without extra libraries:
async function fetchWithNativeFetch() {
  const response = await fetch('https://example.com');
  const html = await response.text();
  console.log('HTML length:', html.length);
}

fetchWithNativeFetch();
Example 3: Scraping JavaScript-Heavy Pages with Puppeteer
Some websites load content dynamically using JavaScript. In these cases, a headless browser is required.
Step 1: Install Puppeteer
npm install puppeteer
Step 2: Puppeteer example (puppeteer-scrape.js)
const puppeteer = require('puppeteer');

(async () => {
  const browser = await puppeteer.launch();
  const page = await browser.newPage();

  await page.goto('https://example.com', {
    waitUntil: 'networkidle2'
  });

  const titles = await page.evaluate(() => {
    return Array.from(document.querySelectorAll('h1')).map(el => el.textContent);
  });

  console.log('Page titles:', titles);

  await browser.close();
})();
What’s happening here
- A headless browser is launched.
- The page is fully rendered.
- JavaScript runs inside the page context to extract data.
Handling Pagination and Multiple Pages
For paginated results, iterate over each URL and reuse the same parsing logic across pages.
const axios = require('axios');
const cheerio = require('cheerio');

const urls = [
  'https://example.com/page/1',
  'https://example.com/page/2',
  'https://example.com/page/3'
];

(async () => {
  for (const url of urls) {
    const response = await axios.get(url);
    const $ = cheerio.load(response.data);
    // Extract data from $ here.
  }
})().catch(console.error);
Common Challenges and Best Practices
Handling Dynamic Rendering
- Static HTTP requests won’t work on JS-heavy sites.
- Use Puppeteer or Playwright for full rendering.
Avoiding Blocks and Rate Limits
- Websites may block scrapers with CAPTCHAs or IP limits.
- Respect
robots.txtand site terms. - Implement delays and retries.
Keeping Code Maintainable
- Separate fetching, parsing, and output logic.
- Use configuration files or environment variables.
- Add proper error handling.
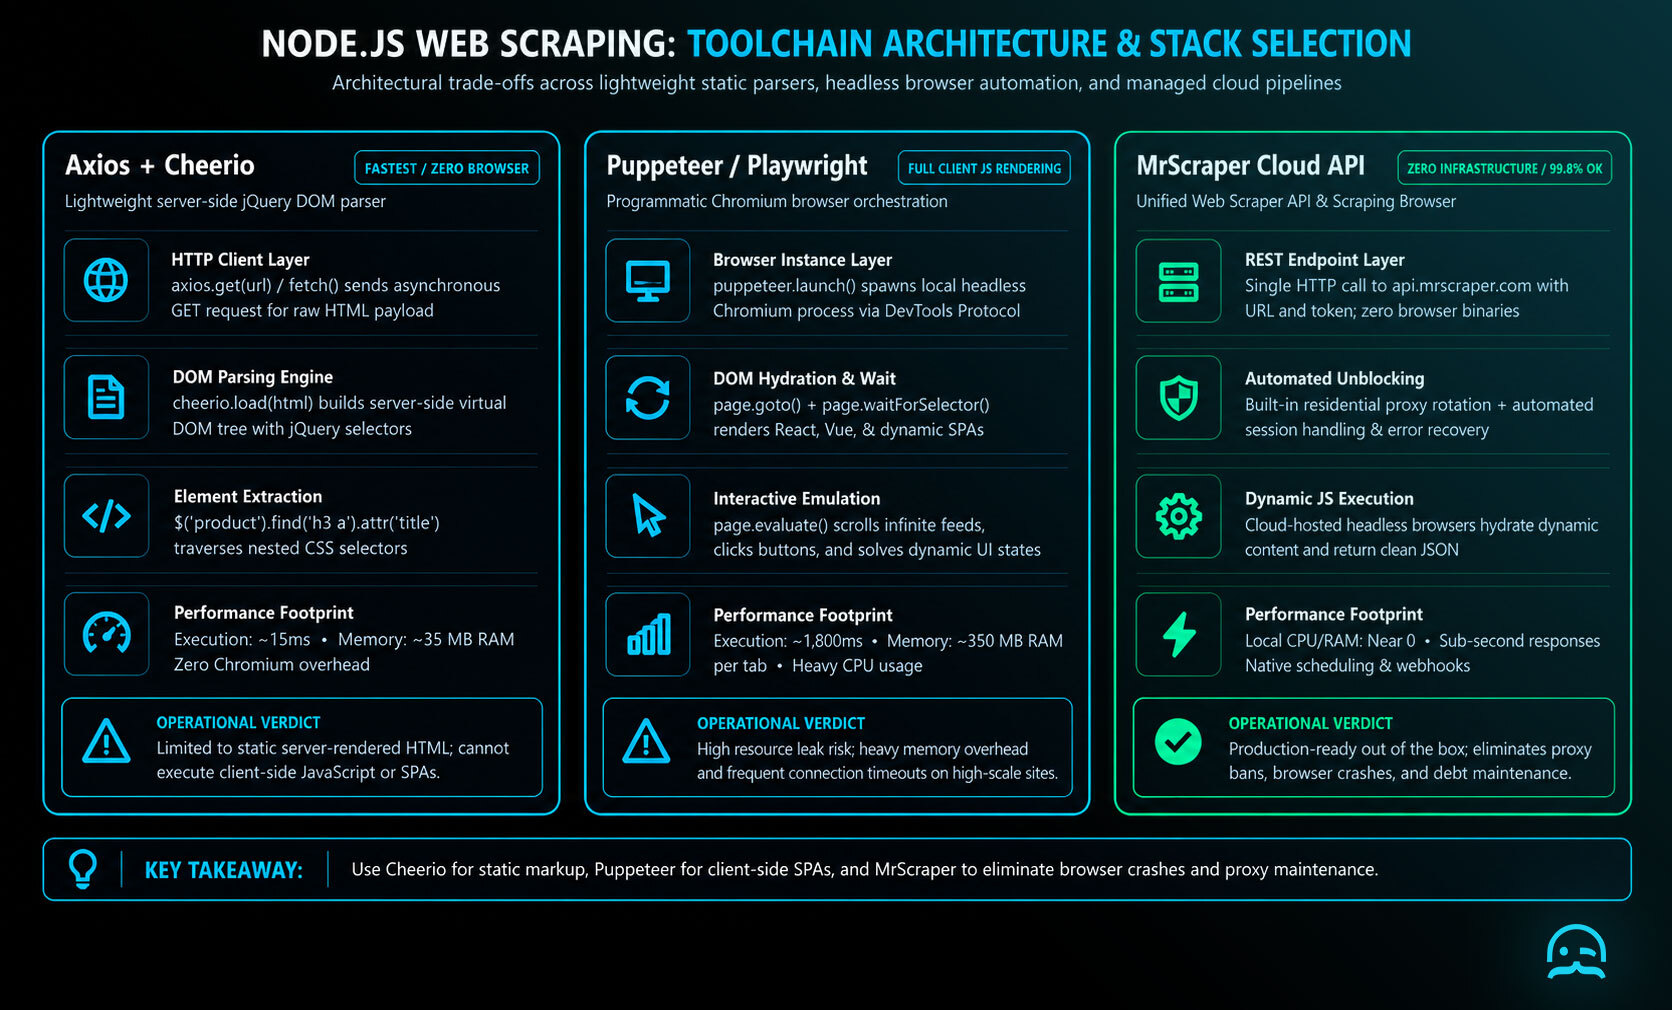
Choosing the Right Tool for Your Scraping Task
| Scenario | Recommended Tool |
|---|---|
| Static HTML | Axios + Cheerio |
| JSON / APIs | Fetch or Axios |
| JS-rendered pages | Puppeteer or Playwright |
Start simple, then scale up as needed.
MrScraper as a Managed Scraping Option
As scraping grows, managing proxies, blocks, and rendering becomes complex.
MrScraper helps by providing:
- Automatic proxy rotation and anti-bot handling
- JavaScript rendering without browser setup
- Structured JSON output
- Scheduling and API-based automation
This allows developers to focus on data extraction rather than infrastructure.
What We Learned
- Node.js works well for web scraping because it uses asynchronous I/O and an event-driven model. It also has many libraries that help collect data efficiently.
- Axios or Fetch with Cheerio works well for static HTML pages. Puppeteer or Playwright is better for pages rendered with JavaScript.
- Maintainable scrapers separate fetching, parsing, and output logic, with configuration and error handling kept distinct.
- Pagination, delays, retries, and respect for robots.txt and site terms are important considerations when scraping multiple pages.
Move from Node.js scripts to managed scraping
Compare plans for a managed scraper when proxy handling, JavaScript rendering, and recurring extraction add infrastructure to your workflow.
Frequently asked questions
Which Node.js tools are used for scraping?
Axios and Fetch can retrieve HTML or data. Cheerio can parse static HTML. Puppeteer or Playwright can handle pages rendered by JavaScript.
Which tool should I use for a static HTML page?
Use an HTTP client such as Axios or Fetch to retrieve the page, then use Cheerio to traverse the returned HTML and extract data.
How do I scrape JavaScript-rendered pages with Node.js?
Use a headless browser such as Puppeteer or Playwright so the page can render its JavaScript before data extraction.
What should a maintainable Node.js scraper include?
Separate fetching, parsing, and output logic. Use configuration files or environment variables. Add proper error handling, delays, and retries.
Now that you know how it works, why not try it yourself?
With MrScraper, you can start collecting web data without building or maintaining your own scraping infrastructure. See how easily you can turn websites into usable data.
Get 1,000 free tokens and start scraping here.
Summarize this post
Open it in your assistant of choice with the prompt ready to send.
Take a Taste of Easy Scraping!

Find more insights here
Claude Code Competitor Pricing Research
Use Claude Code and MrScraper MCP to refresh public competitor pricing, normalize billing periods an…
Use MrScraper MCP to Compare Public SaaS Pricing and Plan Limits
Build a source-backed SaaS plan comparison using MrScraper MCP. Preserve prices, quotas, billing ter…
Build a Product Attribute Classifier with LangChain and MrScraper
Build a LangChain workflow that extracts product evidence with MrScraper, normalizes attributes and…