How to Scrape Dynamic Websites: Future Trends and How to Prepare
Web ScrapingLearn how to scrape dynamic websites while preparing for trends in AI, data quality, ethical practices, scraping-as-a-service, and security.
To scrape dynamic websites well, plan for smarter automation and better data quality. Use ethical methods and service-based tools. Expect new security challenges. Build workflows that are easy to maintain.
1. Increased Use of AI and Machine Learning
To scrape dynamic websites faster, use AI-assisted tools. They automate repeat tasks and free more time for strategic work.
Article. Published June 3, 2024. Estimated reading time: four minutes. Web scraping is crucial for understanding customer behavior, competitor pricing, and market trends. Data and business needs continue to evolve, so understanding future scraper capabilities can help organizations stay ahead. By extracting valuable information from websites, scrapers give companies practical insight for decision-making. As these capabilities and use cases expand, both experienced developers and people just getting started should watch emerging trends and prepare for them.
One important trend is the integration of artificial intelligence and machine learning into web scrapers. These tools can make scrapers smarter and faster. They automate tedious tasks, reduce manual setup, and free developers and analysts for strategic work. The article also anticipates an AI feature for creating a scraper. This capability is expected to help users scrape a website with less effort while making advanced scraping more accessible.
How to Scrape Dynamic Websites
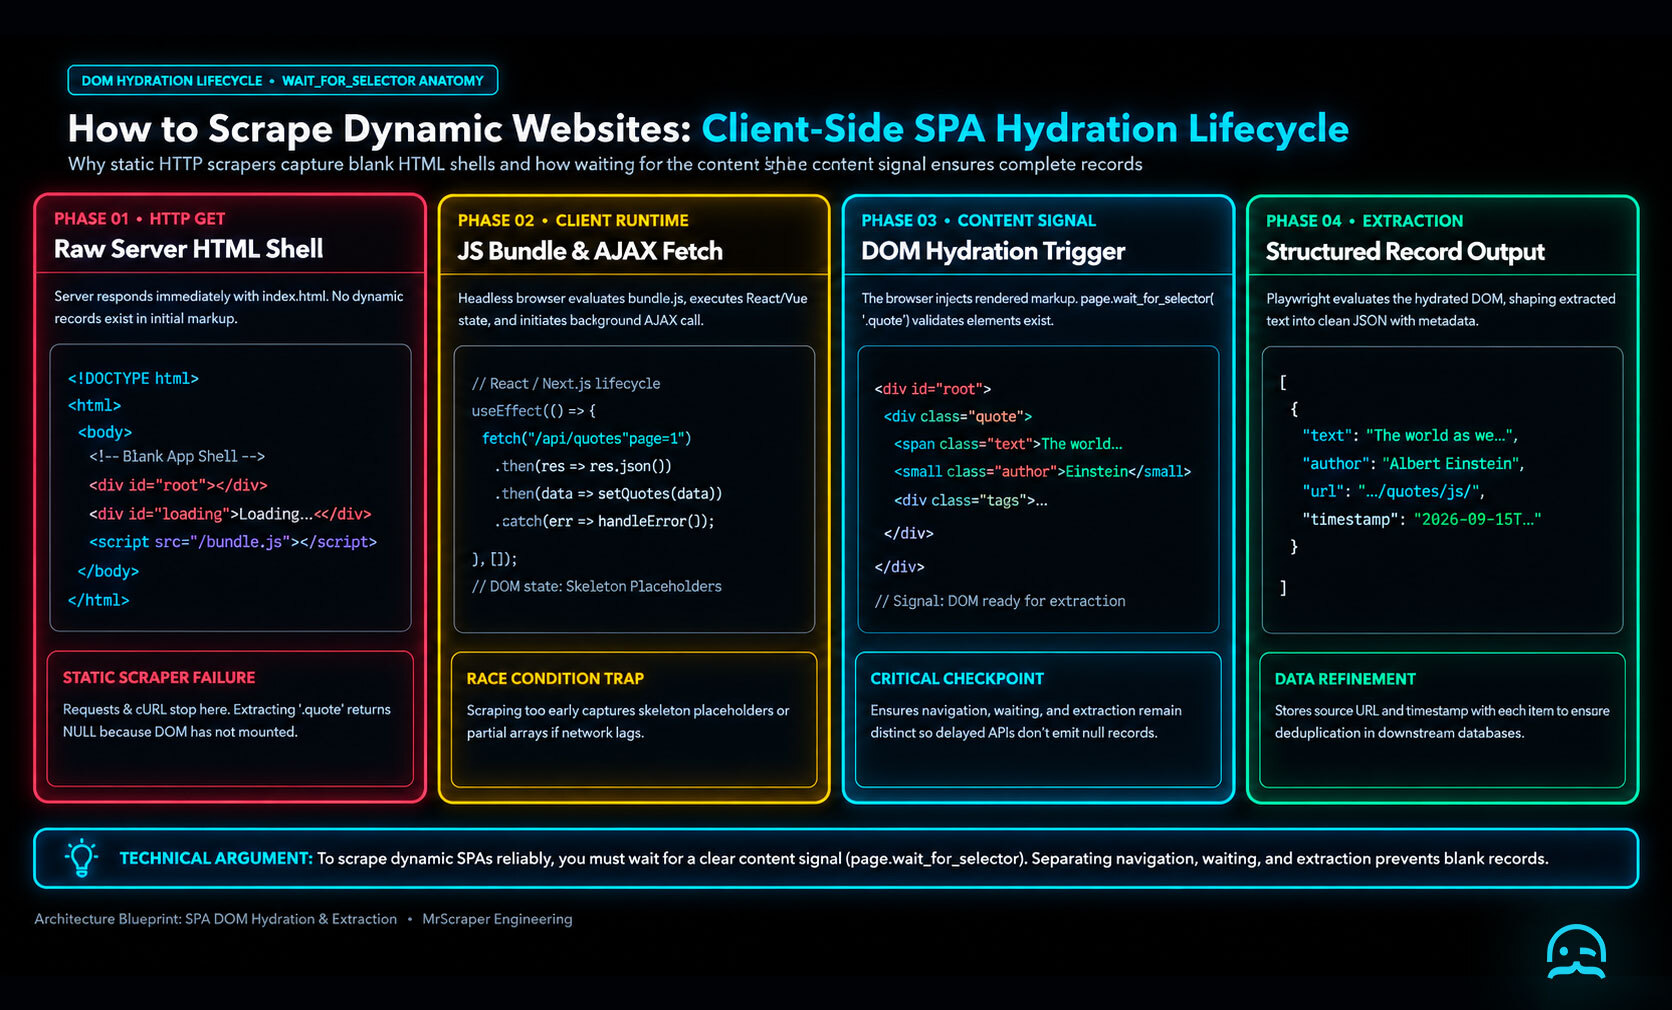
To scrape dynamic websites, load the page in a real browser. Wait for a clear content signal. Then extract the rendered DOM. This approach handles single-page applications whose initial HTML contains little useful data. Keep navigation, waiting, extraction, and validation separate. This way, a redesign or slow API response won’t create empty records.
from playwright.sync_api import sync_playwright

with sync_playwright() as p:
    browser = p.chromium.launch(headless=True)
    page = browser.new_page()
    page.goto("https://quotes.toscrape.com/js/", wait_until="domcontentloaded")
    page.wait_for_selector(".quote")
    records = page.locator(".quote").evaluate_all(
        "els => els.map(e => ({text: e.querySelector('.text').textContent.trim(), author: e.querySelector('.author').textContent.trim()}))"
    )
    print(records)
    browser.close()
Use a stable selector when possible, and record the page URL and timestamp with each result.
2. Enhanced Data Quality and Accuracy
To scrape dynamic websites effectively, treat extraction as the beginning of the data workflow, not the end. As web scrapers improve, data quality and accuracy will matter more. Collected data should be clean, organized, and ready for analysis. You can integrate it with business intelligence platforms. This turns raw records into useful insights. You get more value from your scraping effort. Visual integrations can also send the resulting data to another app through Zapier or Make. This helps teams move it into downstream workflows without rebuilding each transfer by hand.
3. Increased Focus on Ethical Scraping
“With great power comes great responsibility.” The future of web scraping will place greater emphasis on ethical practices, especially when you scrape dynamic websites. That means respecting each website’s terms of service, avoiding excessive server load, and protecting data privacy. Follow the site’s robots.txt rules, which function like a “no trespassing” sign, and send polite requests at a rate that does not overload its servers. Keep scraped data safe and secure, including when it is stored or shared. Ethical scraping helps build trust with websites and supports a long-term supply of valuable data to mine.
4. More Scraping-as-a-Service Platforms
More scraping-as-a-service platforms are emerging as demand grows. These services help users scrape dynamic websites using ready-made tools and easy interfaces, reducing the need to code. This model makes web data extraction easier for non-technical users. It also moves routine scraping work into managed platforms.
5. Enhanced Security Measures
To scrape dynamic websites reliably, future scraper workflows must handle security challenges like CAPTCHAs and IP blocking. They must also manage other anti-automation controls while respecting site policies. More sophisticated techniques will help distinguish legitimate, responsible collection from abusive behavior. Proxy-based approaches can help manage IP blocking. Broader tool support for other security challenges will likely become more important.
You can prepare your strategy for these changes by treating security, compliance, and data quality as connected requirements.
- Prioritize ethical scraping. Follow applicable laws, site terms, robots directives, and reasonable rate limits. Responsible practices help build trust and reduce the risk of website blockages.
- Invest in advanced scraper tools. Choose tools that can handle complex websites, modern anti-scraping measures, and cloud-based deployment. Evaluate how each tool manages authentication, retries, proxy configuration, and failure reporting before adopting it.
- Embrace AI-powered solutions. Explore AI scraper tools that can automate repetitive tasks, identify relevant content, and improve extraction accuracy while leaving important validation decisions under human control.
- Focus on data quality and analysis. Do not stop at collecting records. Clean, validate, analyze, and integrate scraped data so it can support market research, academic studies, or personal projects.
The future of web scraping is still promising, but teams must adapt as sites add stronger defenses and pages become more complex. Security-aware workflows can make collection more efficient and accurate without treating every protection as something to defeat. They can also help organizations turn collected information into usable insights rather than accumulating unverified output.
Keep improving your scraping skills, monitor emerging technologies, and review your collection practices as requirements change. A strategy with ethical safeguards can handle the changing web-scraping landscape. Strong tools and AI-assisted workflows can help. Careful analysis can improve results.
What We Learned
To scrape dynamic websites sustainably, use a prepare-extract-validate-monitor loop. Choose a browser-capable workflow for rendered pages, respect robots.txt and terms, then store structured outputs with timestamps and source URLs. Validate required fields and representative records before sending data to analysis or integrations.
The guide’s main takeaway is balance. AI can reduce repetitive setup. Quality checks make results useful. Ethical limits protect access. Hosted platforms simplify operations. Proxy support helps address blocking. Revisit selectors and validation rules when page behavior changes. For broader context, Firecrawl's dynamic scraping tools overview is a useful reference.
How to Scrape Dynamic Websites
import asyncio
from playwright.async_api import async_playwright

async def main():
    async with async_playwright() as p:
        browser = await p.chromium.launch()
        page = await browser.new_page()
        async with page.expect_response(
            lambda r: "/api/products" in r.url
        ) as response_info:
            await page.goto("https://shop.example/catalog")
        response = await response_info.value
        products = await response.json()
        print(products)
        await browser.close()

asyncio.run(main())
Prepare Your Web Scraping Workflow
Explore a practical starting point for automating data extraction workflows as you prepare for evolving scraping needs.
Summarize this post
Open it in your assistant of choice with the prompt ready to send.
Take a Taste of Easy Scraping!


Find more insights here
Why MrScraper is the Best ScraperAPI Alternative for No-Code Users
Compare ScraperAPI alternatives and discover why visual, AI-powered extraction is better for no-code…
Building Sustainable Revenue Engines through AI-Enhanced Data Scraping
Learn how AI-powered data extraction software and residential proxies build sustainable revenue engi…
MrScraper vs ScraperAPI: Which Scraping API Wins in 2026?
Compare MrScraper vs ScraperAPI. Learn how AI-powered selectors and native scheduling reduce the tot…